Interaction交互
We conduct systematic research on embodied intelligent human–robot interaction and have built an integrated framework covering perception, cognition, generation, and execution. The framework fuses multimodal information such as vision and audition, and coordinates the generation and real-time control of facial expression, speech, lip motion, and body movement.
围绕具身智能人机交互开展系统性研究,构建了覆盖“感知—认知—生成—执行”的一体化交互框架,实现视觉、听觉等多模态信息融合,以及表情、语音、口型和肢体动作的协同生成与实时控制。
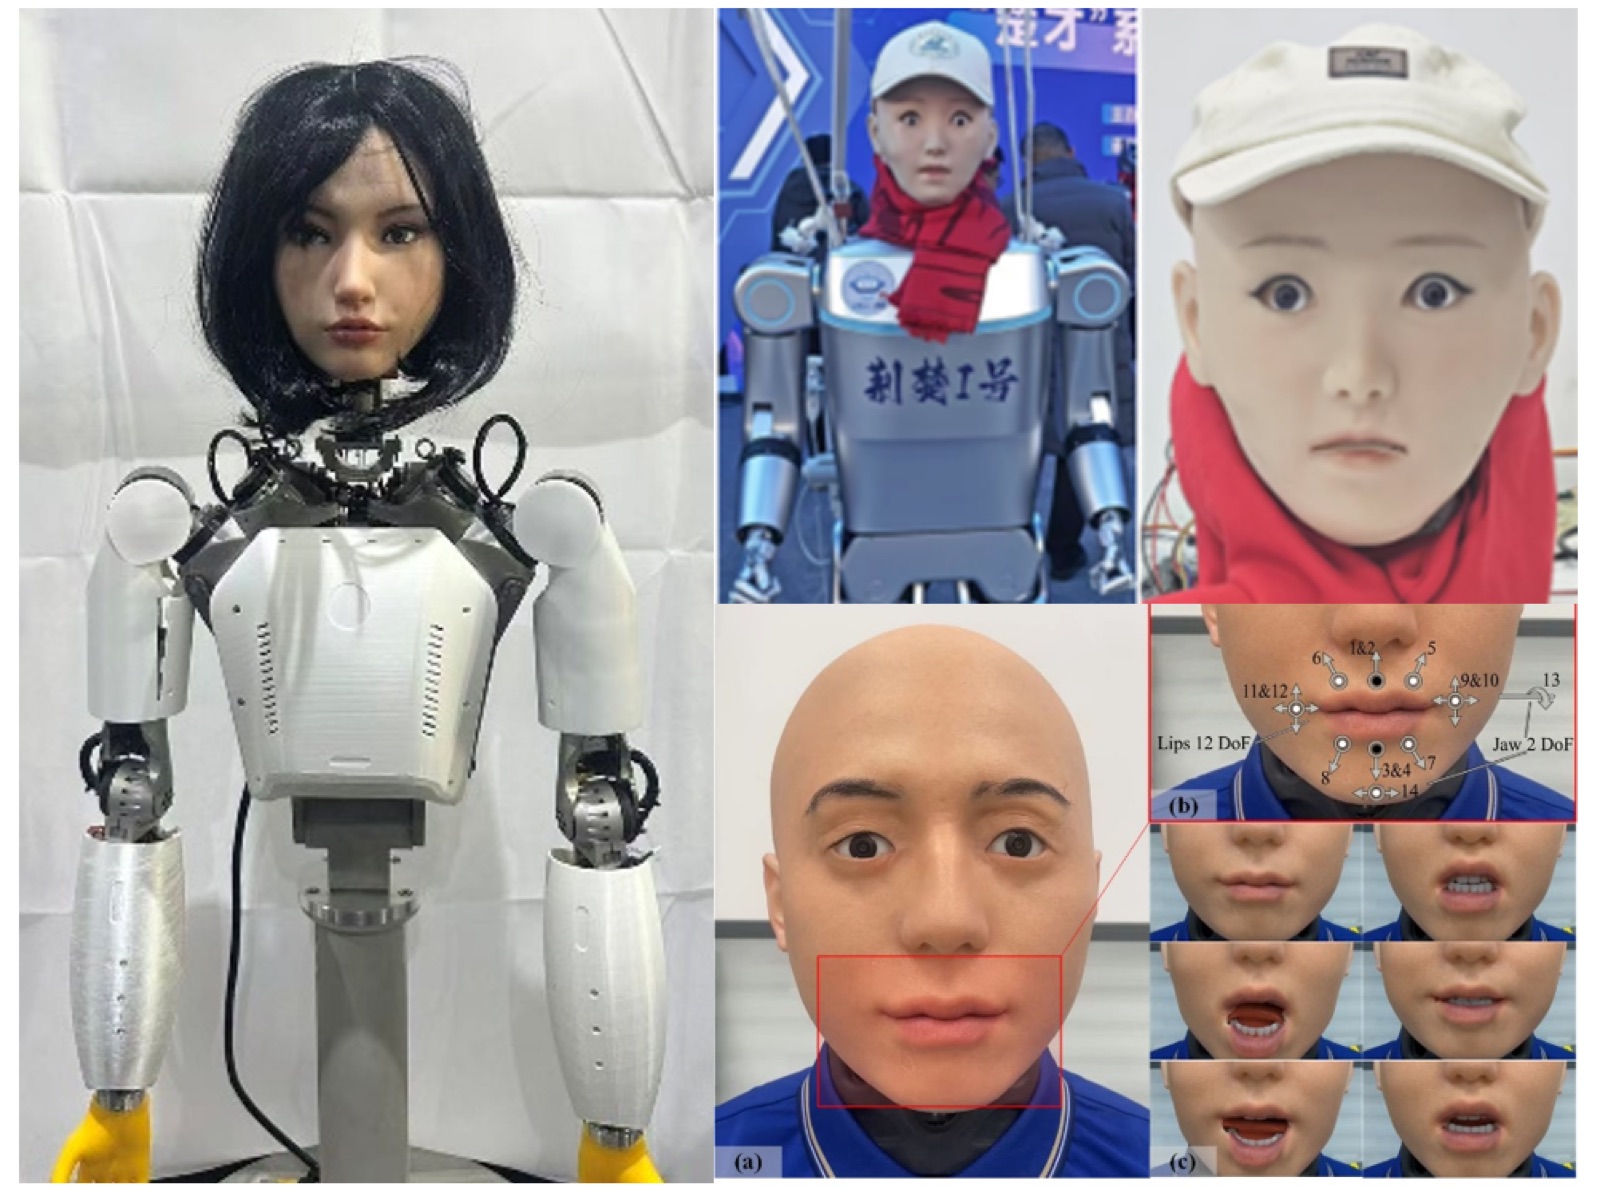
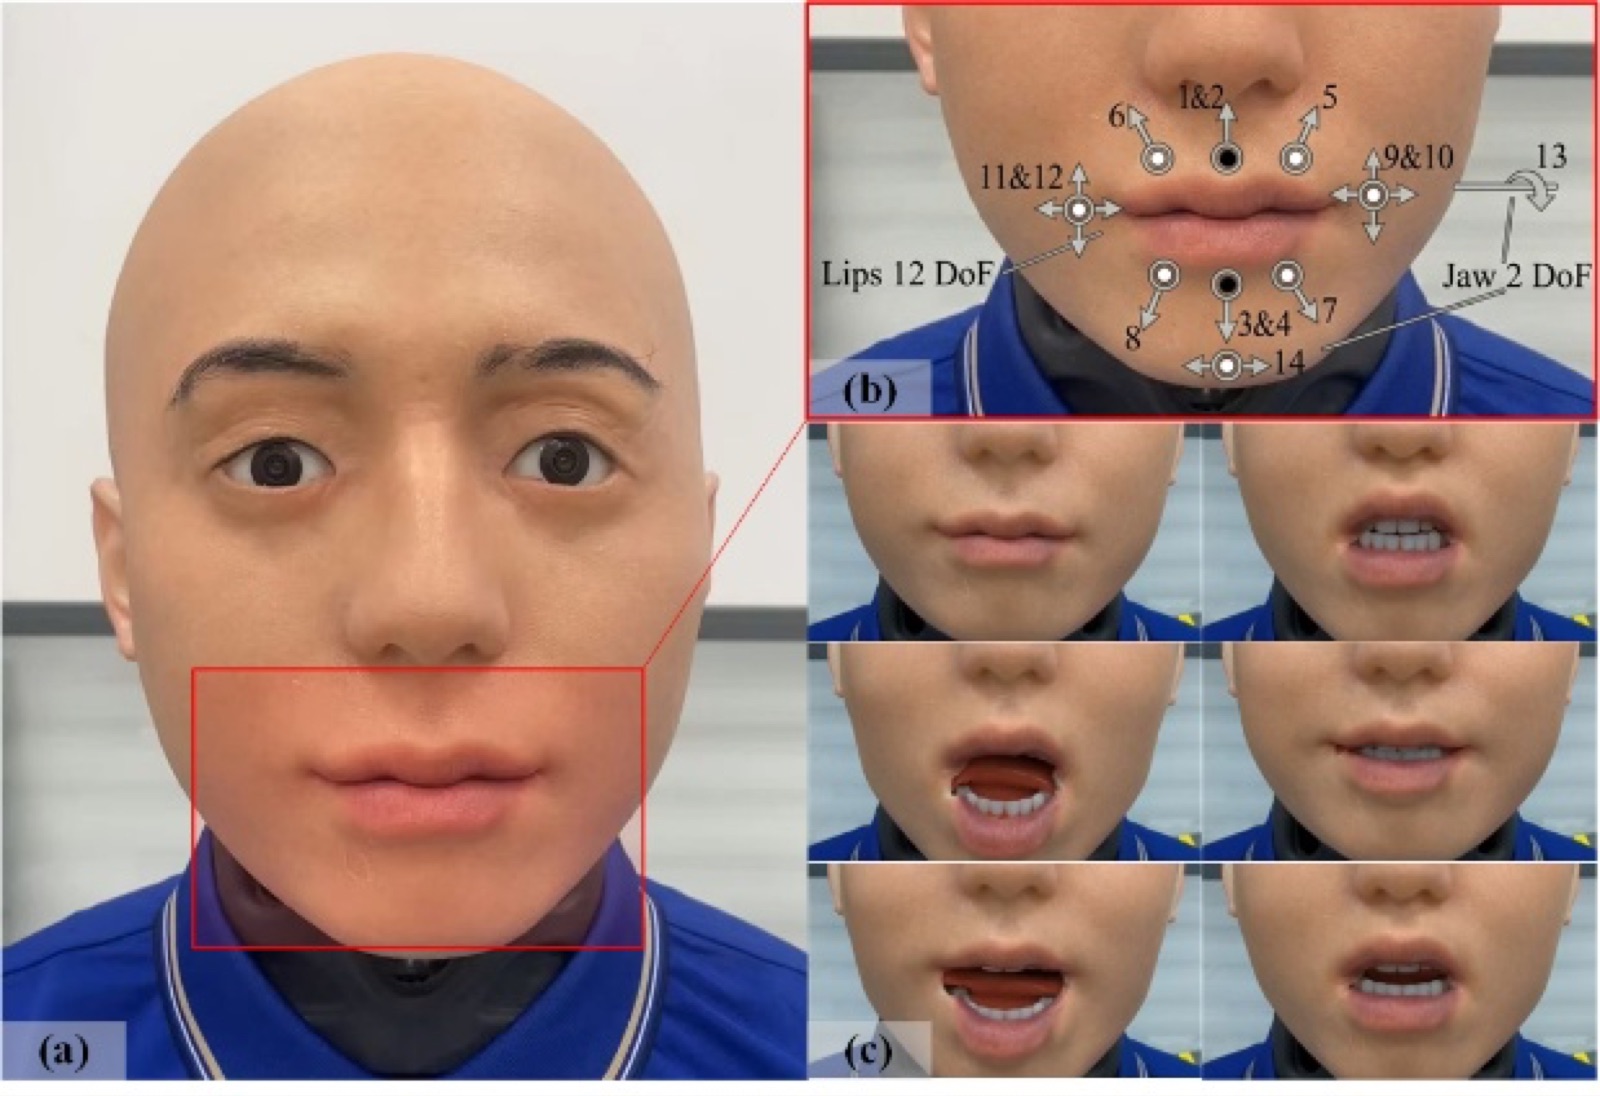
The team independently developed a fifth-generation highly biomimetic humanoid robotic head with rich sensing and high-fidelity affective expression. It has been deployed on platforms such as the Jingchu robot. To support natural interaction, we continue to advance key technologies including continuous emotion modeling, speech-driven lip generation, and multimodal motion generation, enabling more natural, fluent, and emotionally expressive communication.
These results have been demonstrated in intelligent guiding, education, and media interviews, showing strong interaction quality and application potential.
团队自主研发了第五代高仿生人形机器人智慧头部,具备丰富的感知能力和高保真情感表达能力,并已成功应用于荆楚机器人等平台。围绕自然交互需求,实验室持续突破连续情感建模、语音驱动口型生成、多模态动作生成等关键技术,使机器人能够实现更加自然、流畅、富有情感的人机交流。
相关成果已在智能导览、教育教学、媒体采访等多个场景完成示范应用,展现出良好的交互体验与应用潜力。